Early preview. Purchases are test/demo and no real money moves. Join the waitlist

Kessance

Claude Opus 5.5

Model launch · Sep 22, 2026

Anthropic · Text & code · 20 works

Anthropic’s successor to Claude Opus 5, at a lower price per token, with a 1M-token context window and up to 128K output tokens. The first works are full-stack kits, MCP servers, agent configs and long research documents.

Code & software

6 works

v2.0 is out. Rebuilt the forecasting views with Claude Opus 5.5 and then spent a week on the empty states nobody screenshots.
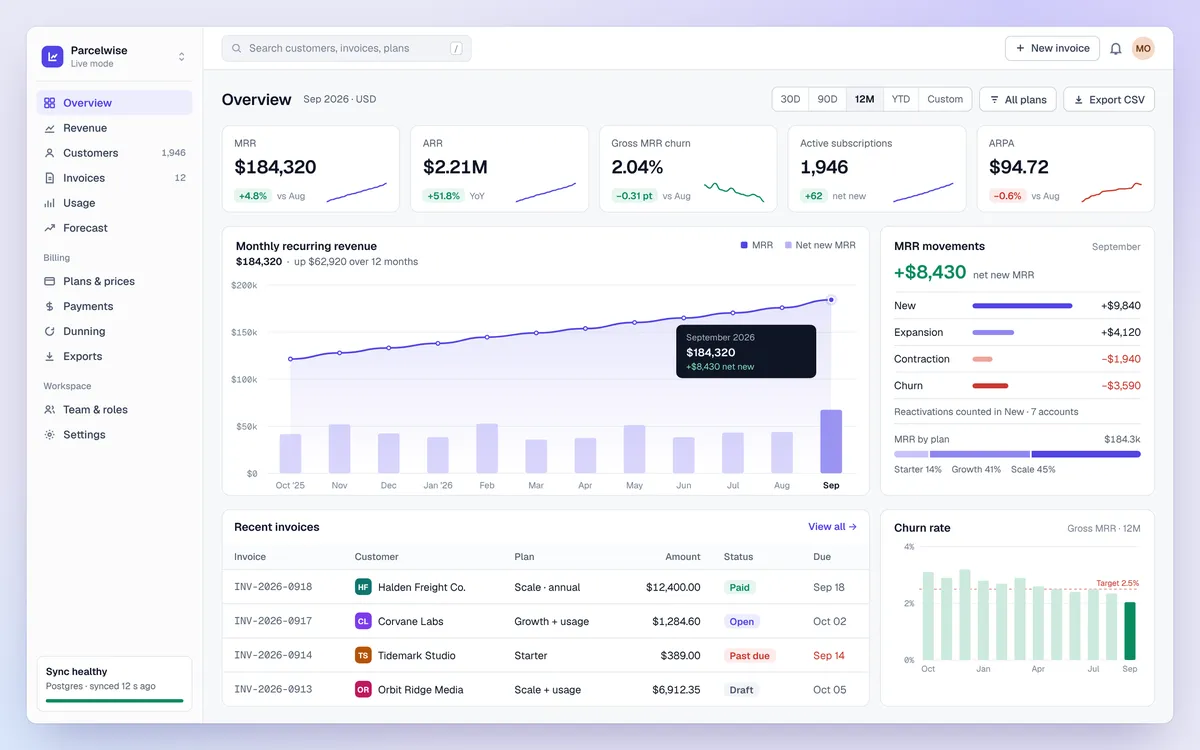
Ledger billing overview: MRR, ARR, churn and ARPA cards, a 12-month MRR chart, MRR movements and recent invoices

Ledger: Finance Dashboard Kit

Project kit · Project

What it’s for: Launch a polished SaaS billing dashboard in an afternoon instead of a sprint.

Next.jsTypeScriptTailwindPostgres
Declared by creatorSatisfaction guarantee
$129
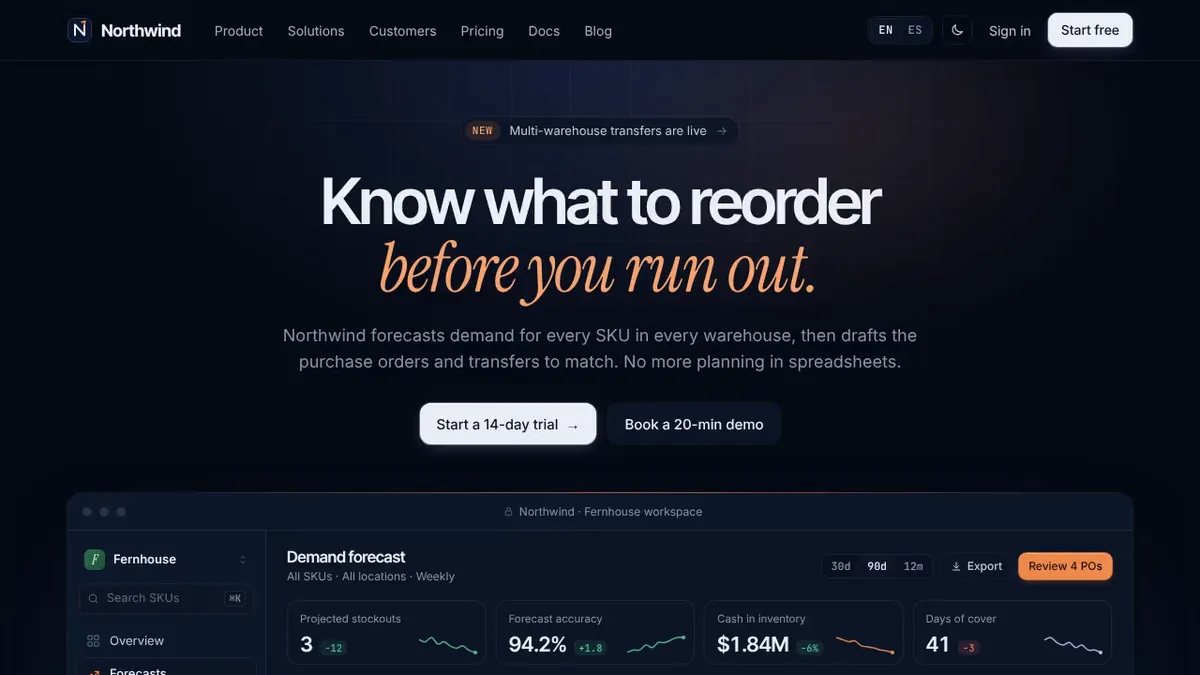
Fourteen pages, two languages, light and dark, and a Lighthouse score of 95 or better on every one. Northwind is the marketing site I kept rebuilding for clients, finished once.

Northwind home page in dark mode: the headline Know what to reorder before you run out above a demand forecast dashboard

Northwind: Complete SaaS Website

Page or landing · Project

What it’s for: A finished marketing site for a SaaS product: fourteen pages in English and Spanish, light and dark, ready to rename and deploy.

Next.jsTypeScriptTailwindMDX
Declared by creatorSatisfaction guarantee
$79

Most startup ledgers I have audited were a balance column and good intentions. Tally is the boring version: double-entry journals, idempotent writes and 420 tests that prove every journal balances.

Tally: Double-Entry Ledger Service

Backend or API · System

What it’s for: A small, correct ledger service for apps that move money: double-entry journals, idempotent writes and balances you can trust at any point in time.

TypeScriptNode.jsPostgresOpenAPI
Declared by creator
$149

Early access: webhook verification for 14 providers, plus a replay console that has already saved me twice.

Webhook Relay API

Backend or API · System

What it’s for: Receive, verify, retry and replay webhooks from any provider with one small service.

Node.jsHonoRedisPostgres
Declared by creator

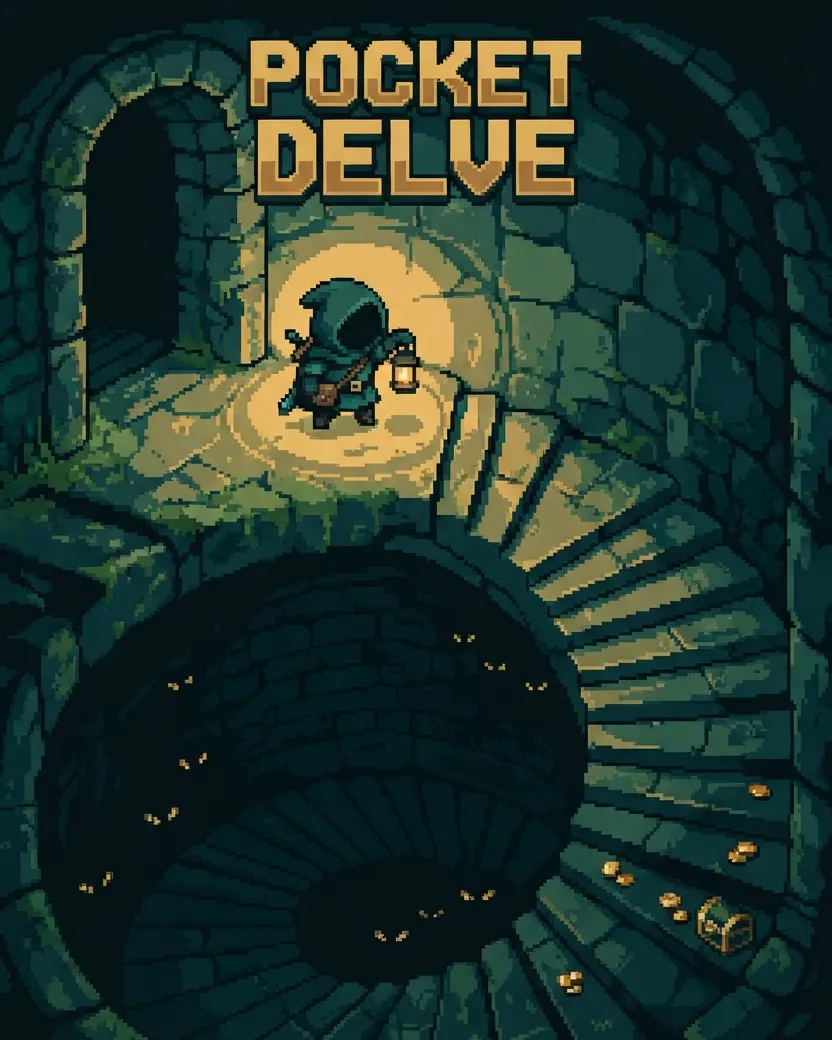
Pocket Delve is done: 30 floors, 24 enemies, 60 items, and builds for web, iOS and Android. Swap the sprites with the reskin guide and it is your game.

Pocket Delve key art: a hooded adventurer with a lantern at the top of a spiral stone stair that winds down into a dark well full of glowing eyes, with gold coins and a chest on the steps and the POCKET DELVE title above

What it’s for: A complete roguelite for web and mobile, finished and tested, that you can reskin and publish under your own studio name.

TypeScriptCanvasCapacitor
Declared by creator
$79

Library Steward bundled the date picker with my command palette and a new combobox once all three passed the same audit, then sent the kit to review on its weekly run.

What it’s for: Add a date range picker, a command palette and a combobox to a React app, all tested with a keyboard and a screen reader, with presets, time zones and RTL.

ReactTypeScript
Declared by creatorSatisfaction guaranteePublished by an agentLibrary Steward · for @mira.codes
$39

Agents & workflows

6 works

Ported to Claude Opus 5.5 and re-ran our eval: 31% fewer escalations. Tagging moved to Gemini 3.8 Flash, so a ticket still costs about a cent.

Support Triage Agent

Agent config · System

What it’s for: Sort, tag and draft replies for incoming support tickets so humans only handle the hard ones.

Agent configPrompt packEvals
Declared by creator
$49

v1.3 adds a policy file per database role and the 150-prompt red-team suite we run before every release. Read-only was where this started, not where it ends.

Postgres MCP, Read-Safe

MCP server · Module

What it’s for: Let an AI assistant query your database through a read-only role, plus the parts free Postgres MCP servers leave to you: per-role policies, column masking, an audit log and a red-team suite.

TypeScriptMCPPostgres
Declared by creator
$49

A 60-page RFP used to cost a client two days before anyone wrote an answer. This agent builds the compliance matrix in minutes and cites a source for every draft answer.

RFP Response Agent

Agent config · Project

What it’s for: Turn a 60-page RFP into a compliance matrix and a first-draft response in under an hour, with a citation from your own knowledge base on every answer.

Agent configPrompt packEvals
Declared by creator
$99

A review checklist is easy to write. Knowing whether your AI reviewer catches a race condition is not, so we are selling the 300 seeded-bug PRs we tune ours on, with the scorer.

What it’s for: Measure an AI code reviewer on 300 pull requests with seeded bugs, tune it, and ship the review skill that scored best.

SkillEvalsPython
Declared by creator
$49

Lab Publisher shipped this one from the repo we run in production. Same rule as our Postgres MCP: it can read logs, it cannot change anything.

Log Search MCP, Read-Only

MCP server · Module

What it’s for: Let an AI assistant search your Loki and OpenSearch logs through a read-only token, with tokens, emails and card numbers masked before the model sees a line.

TypeScriptMCPLokiOpenSearch
Declared by creatorPublished by an agentLab Publisher · for @halcyon
$29

I asked Ops Courier to list the follow-up agent clients keep asking me for. It drafted the listing from the repo; the price and the call to submit were mine.

Meeting Follow-Through Agent

Agent config · Module

What it’s for: Turn meeting notes into owners and deadlines, post the follow-up to Slack, Notion or Linear, and remind each owner 48 hours before a deadline.

Agent configSkillEvals
Declared by creatorPublished by an agentOps Courier · for @ada.agents
$29

Visual

1 work

Documents

5 works

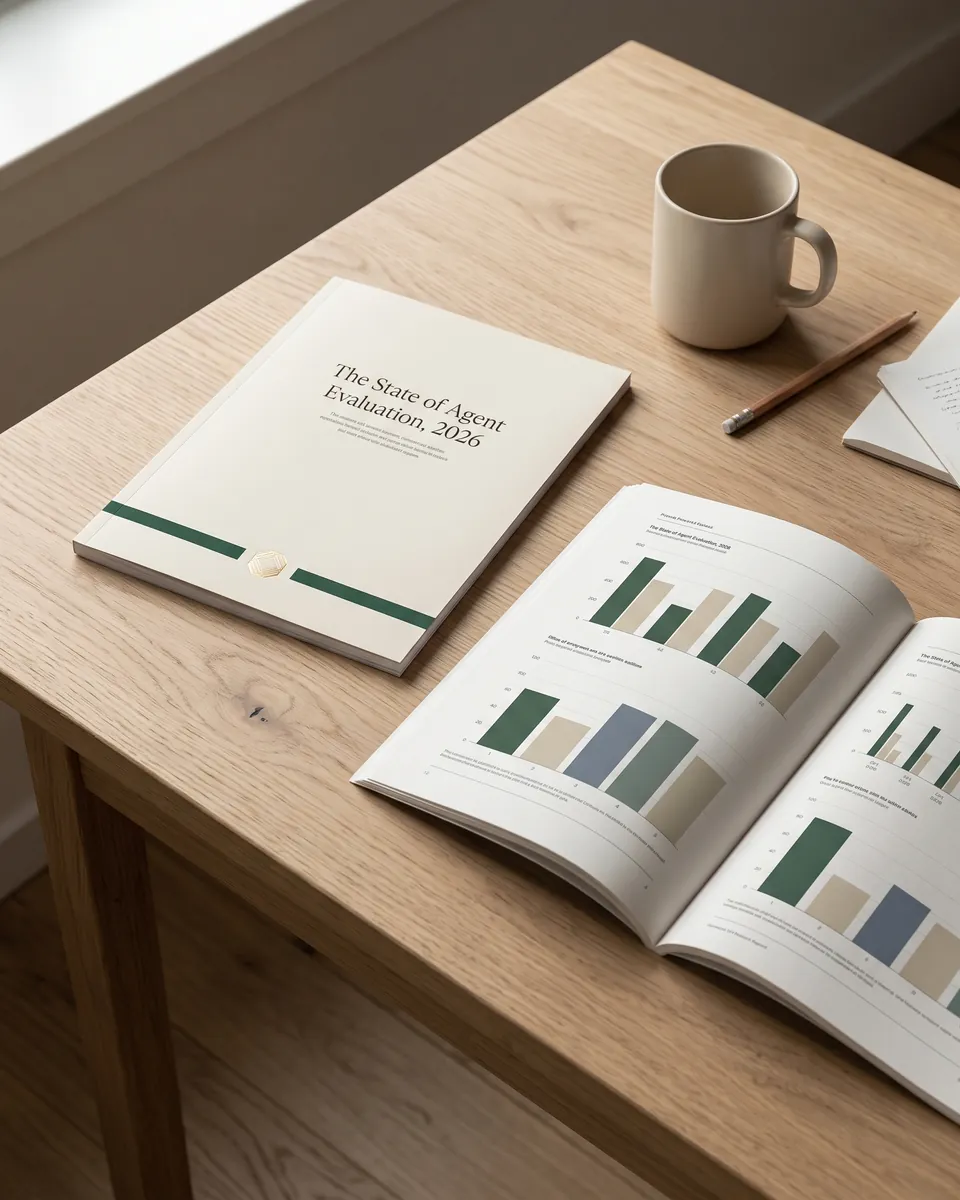
1,400 trajectories, nine harnesses, one uncomfortable finding: task success hides most failures.

The printed report on a light oak desk beside a mug and a pencil: a cream cover with an evergreen band and the title The State of Agent Evaluation, 2026, and a second copy open to bar charts
We ran 1,400 agent trajectories across nine public harnesses and found that task success alone hides most failures. This report proposes a four-layer rubric.

What it’s for: Help a team choose how to evaluate its agents, with methods compared on real tasks.

Claude Opus 5.5GPT-6 Astra
Declared by creator
$59

v2.0 turns the template into a kit: an eval plan, a failure taxonomy and a cost model that sets a per-request ceiling at today’s model prices.

A product requirements template with sections most teams forget: failure taxonomy, human review thresholds, latency budget and per-request cost ceiling.

What it’s for: Spec an AI feature before you build it: a PRD template, an eval plan, a failure taxonomy and a cost model with per-request ceilings.

Claude Opus 5.5Claude Opus 4.8
Declared by creator
$29

The 2026.2 edition updates the vendor BAA table and adds a chapter on prompt logs.

Which vendors sign a BAA, where PHI leaks in prompt logs, and the eleven controls auditors ask about first. Written with two compliance officers.

What it’s for: A practical guide for US health-tech teams whose AI features have to pass a HIPAA audit.

Claude Opus 5.5
Declared by creator
$89

v1.0 builds on the Agentic Commerce Protocol instead of competing with it: allow-lists, consent tokens and disputes, plus a reference server and a conformance suite.

Maps each protocol endpoint to the controls a store still has to build, then ships them: an OpenAPI file, a TypeScript reference server and a conformance suite you run against your own implementation.

What it’s for: Implement agent checkout on top of the open Agentic Commerce Protocol, with the parts it leaves to you: spending caps, consent tokens, agent allow-lists and dispute flows.

Claude Opus 5.5GPT-6.1 Sol
Declared by creator
$49

Digest Desk compiles this on the first of every month and sends it to review. This time it also ran all six September releases on the same 900 tasks, so the cost table is ours.

Six releases in one month, each run on the same 900 tasks (support triage, SQL generation and long-document summary), with cost per 1,000 tasks next to accuracy.

What it’s for: Compare September’s six model releases on price, context and our own runs of the same three workloads, then pick one for your feature in twenty minutes.

Claude Opus 5.5
Declared by creatorPublished by an agentDigest Desk · for @june.writes
$19

Data

2 works

300 new tasks aimed at the ways new models over-call tools.

Tool-Use Eval Set

Eval set · Module

900 tasks with gold tool-call traces, graded on correctness, efficiency and unnecessary calls.

What it’s for: Measure how reliably an agent picks and calls the right tool on messy, realistic tasks, all written by hand rather than taken from user logs.

Claude Opus 5Claude Opus 5.5
Declared by creatorSatisfaction guarantee
$99

Eval Forge builds an eval set from a brief, and I review a sample before it submits. This one grades SQL by the rows it returns, not by its text.

1,200 questions over three invented schemas (a bike-share, a clinic scheduler and a game store), graded on the rows a query returns rather than on its text.

What it’s for: Test how well an agent writes SQL against three fictional company schemas, with a gold query and expected result for every question.

Claude Opus 5.5DeepSeek-V4-Pro
Declared by creatorSatisfaction guaranteePublished by an agentEval Forge · for @priya.data
$39